Historical benchmarks
August 20, 2026 CFA JSON Schema run
The following preserves the source-backed historical report at GLRMask f9f5c84. It is a composite AWS result with different revisions, hardware, tokenizer and repeat policy from the current Mac benchmark. Do not compare its numbers directly to the October 8 tables.
This is the preserved August 20, 2026 composite engineering benchmark. It is an official-population view of the historical CFA run, not the final native-Rust publication sweep.
Population
All figures and statistics in this report use exactly the 9,558 schemas in JSONSchemaBench’s official data/ tree at commit:
ba103c73756198dd9b149ddc7db7867da7a077f6The corresponding MaskBench payloads supply examples/tests. The historical CFA sweep originally also contained 705 MaskBench-only additions:
147  Handwritten---*
413  Synthesized---*
100  JME_*
 45  MCPspec---*
Those 705 cases are excluded from every number and graph shown here. BFCL was already separate and was not part of the historical 10,263-case sweep.
The official-population view contains 9,558 problems. GLRMask built 8,826; llguidance built 8,828. Runtime measurements exist on 7,976 GLRMask problems and 7,977 llguidance problems; the paired runtime population contains 7,970 problems.
Historical run and correction provenance
The original full sweep ran on AWS m8azn.3xlarge in us-east-1c, with 12 physical vCPUs and 48 GiB RAM on the M8azn AMD EPYC 9R05 family. Relevant settings were:
- one measured timing traversal;
- zero per-schema warmup traversals;
- one build attempt;
- Linux thread-CPU runtime timing;
MIMALLOC_PURGE_DELAY=-1;- CFA
895d8816b6edd5757e7afa398f47c2787f901312; - original GLRMask tree
42f4d1cc4a1f9e5672c3c01f976b1d36db3152a9; - llguidance 1.6.1.
A deterministic first-commit latency bug was subsequently found in GLRMask’s post-deserialization path. After Constraint::load(), an empty wide-frontier cache could still force deferred dynamic-vocabulary materialization during the first commit. The fix is GLRMask commit 86a9b8ba06e58f4e2750e1f27894c19253f2464b (Avoid lazy vocab materialization for empty wide frontiers).
To preserve the original build measurements while correcting that runtime artifact, every problem whose original pre-fix maximum GLRMask TBM was at least 25 µs was rerun on a same-family AWS m8azn.xlarge (4 physical vCPUs / 16 GiB, same AZ). The two targeted reruns cover 1,292 unique problems. Only GLRMask runtime mask/commit/TBM arrays were replaced. Original build/TTFM fields, llguidance data, semantic results, token identities, and all non-target runtime records were retained.
The splice was audited against the rerun artifacts and the original pre-splice backup. All original build/framework dictionaries remained unchanged; target runtime arrays matched the reruns exactly; non-target records were unchanged.
The underlying historical timing chunks remain the expanded 10,263-problem artifact. The official 9,558 statistics and plots are a verified structural filter using the exact official JSONSchemaBench ID set. No duplicate filtered timing copy is retained.
This is therefore intentionally a composite engineering result, not a single-host, single-revision publication run.
Corrected TBM distribution — official 9,558 only
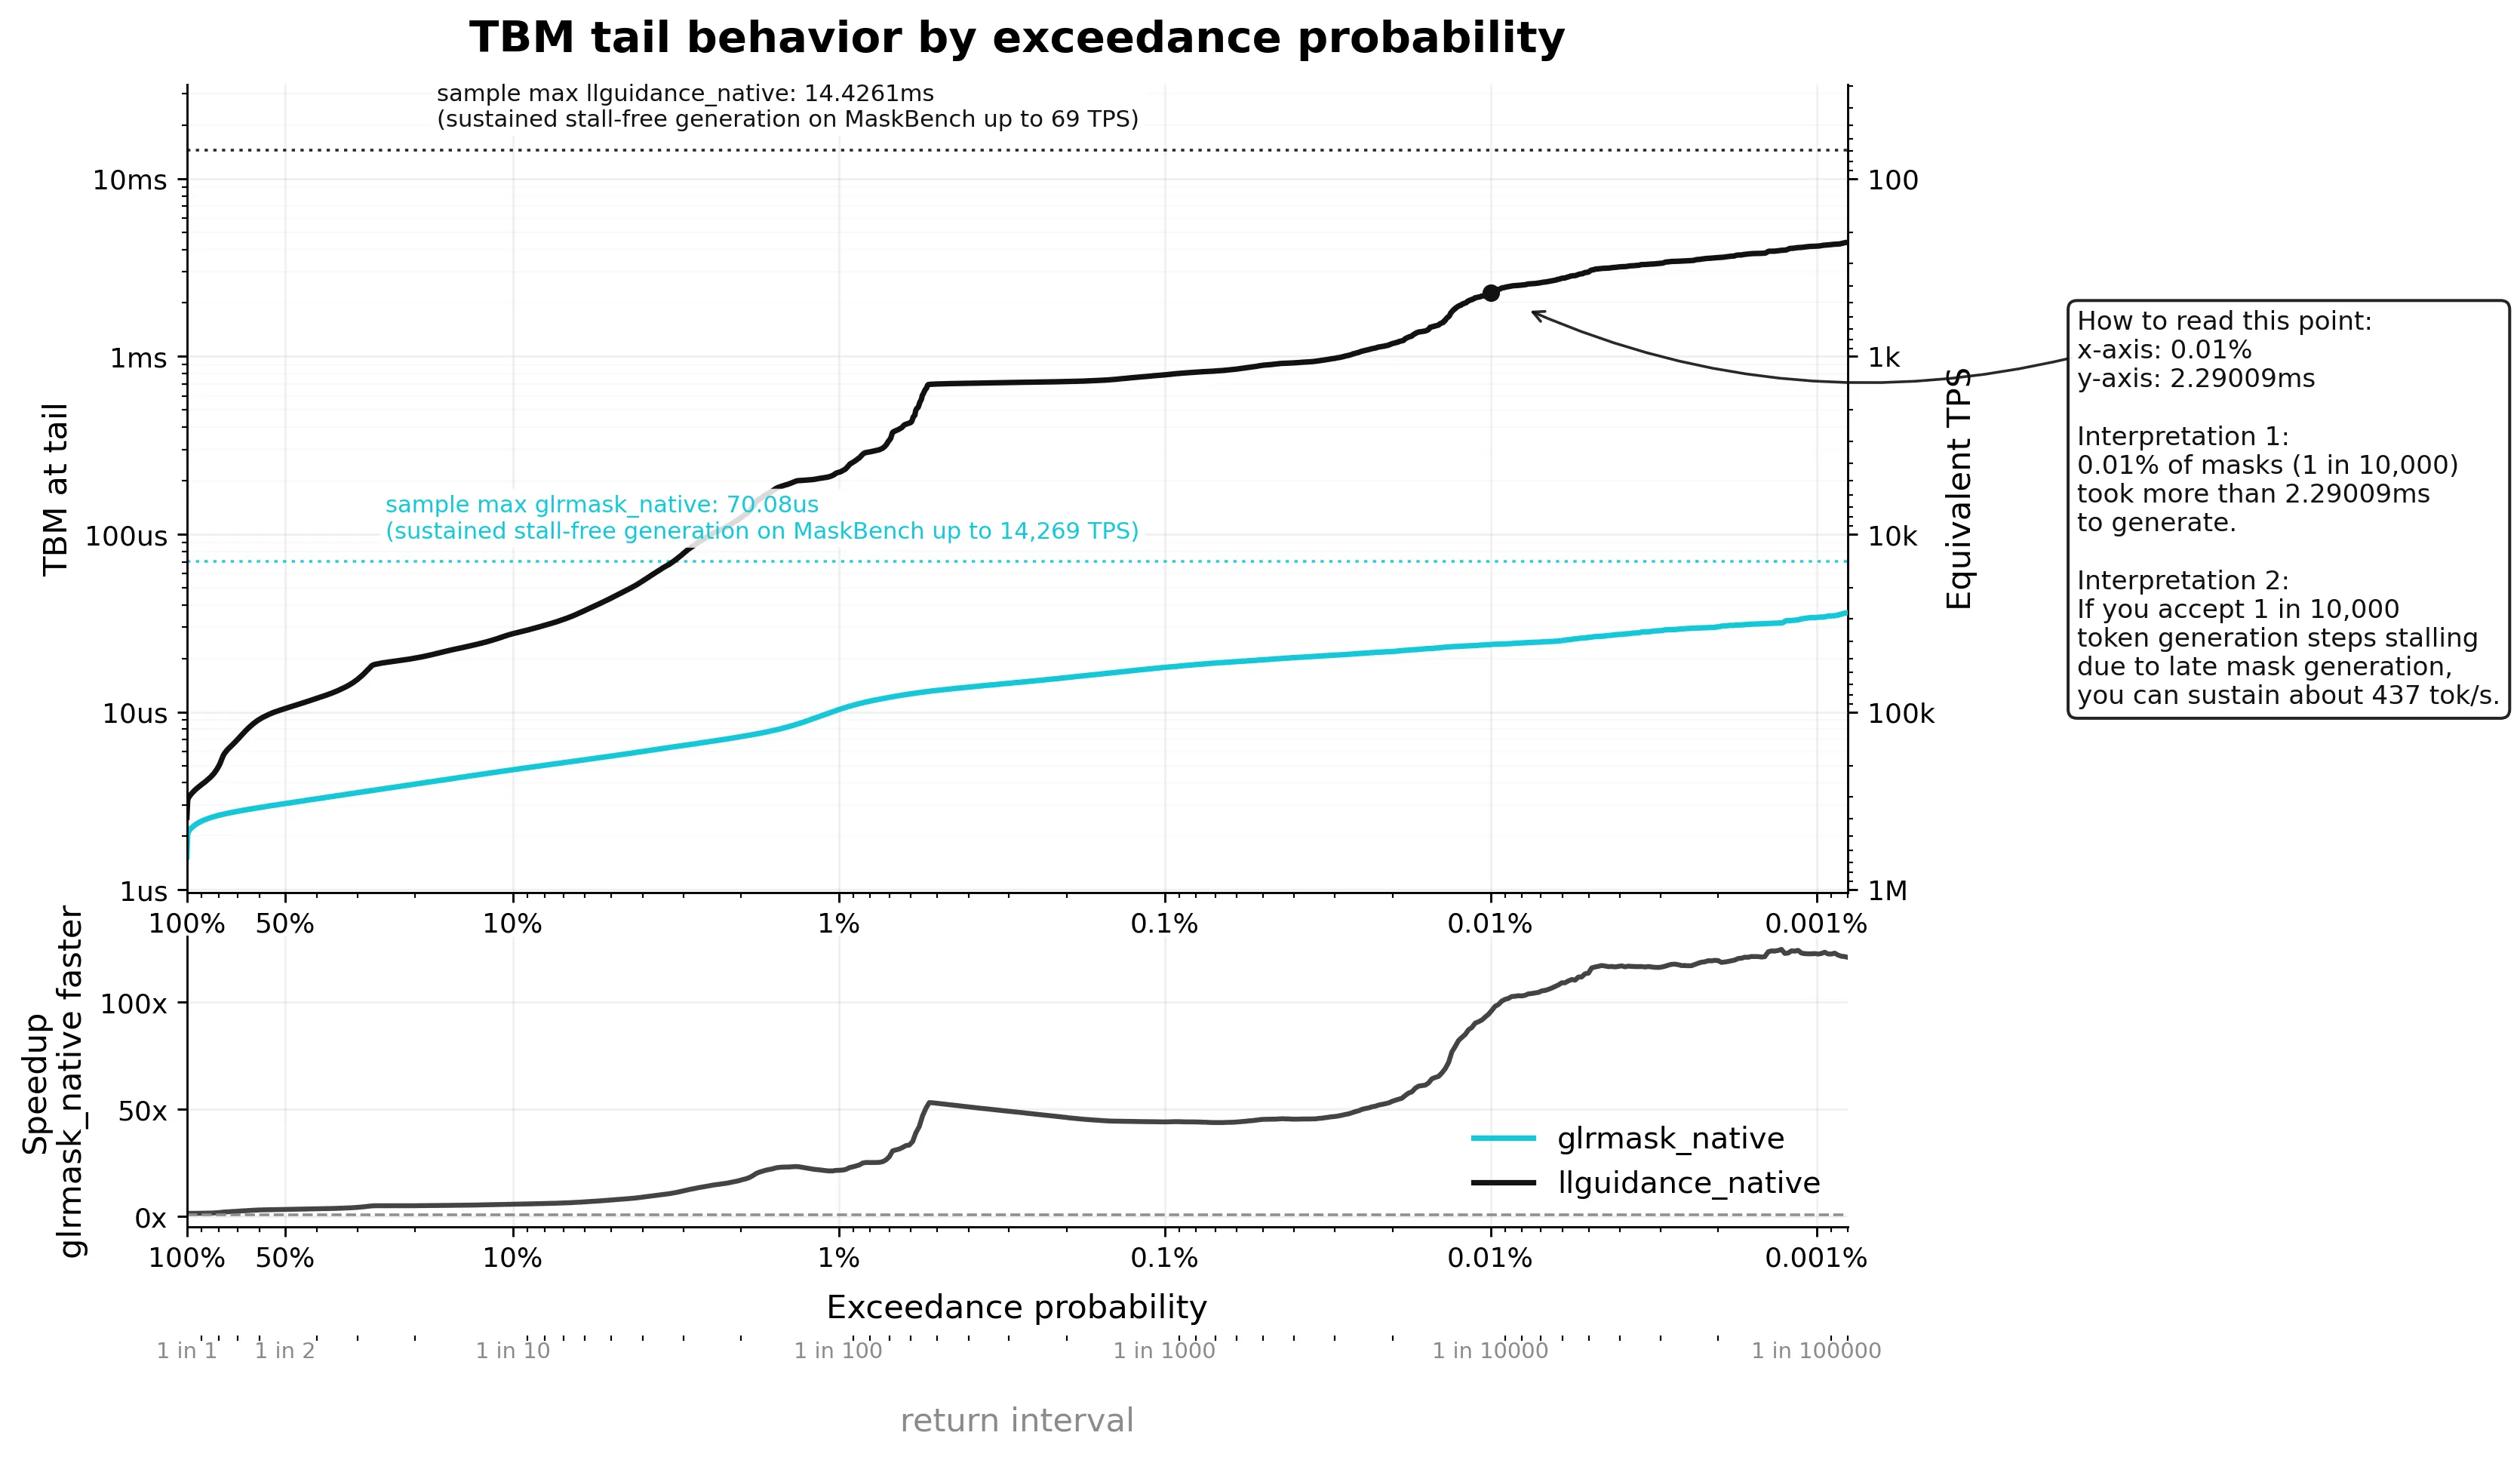
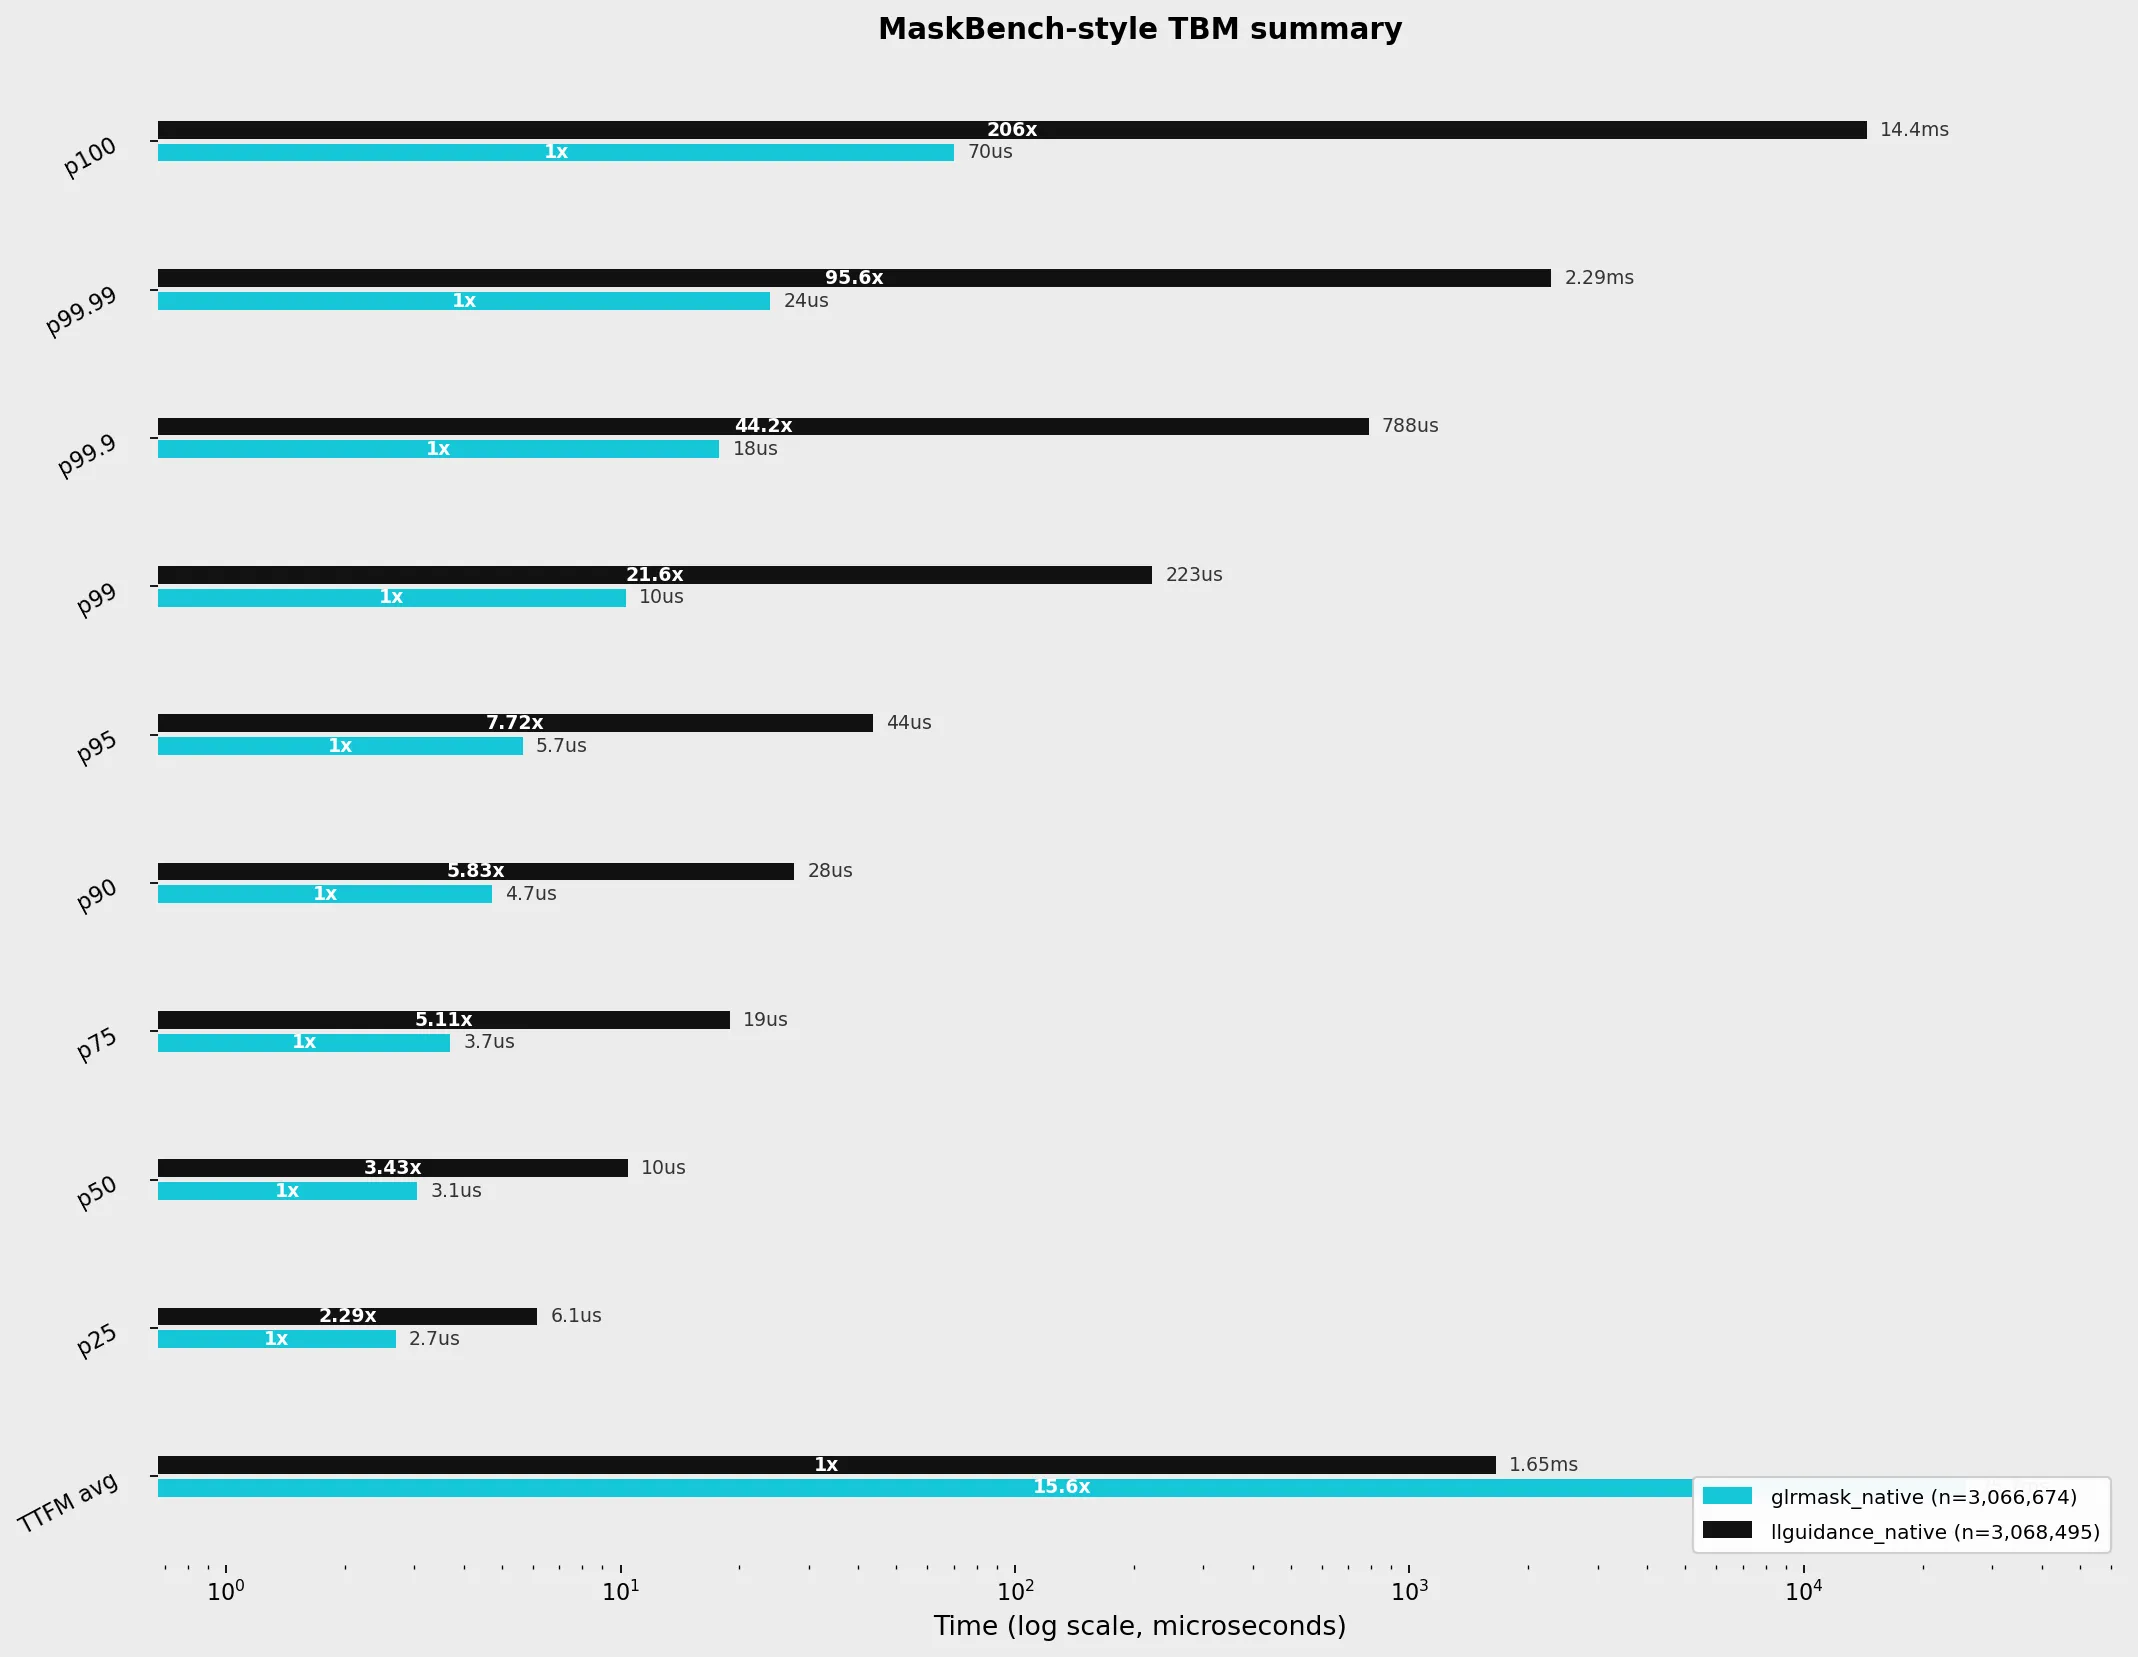
Microseconds. TBM is the old CFA metric: measured mask time plus commit time for one token transition.
| TBM | GLRMask | llguidance |
|---|---|---|
| mean | 3 µs | 21 µs |
| p50 | 3 µs | 10 µs |
| p90 | 5 µs | 28 µs |
| p95 | 6 µs | 44 µs |
| p99 | 10 µs | 223 µs |
| p99.9 | 18 µs | 788 µs |
| p99.99 | 24 µs | 2,290 µs |
| maximum | 70 µs | 14,426 µs |
Measured TBM sample counts:
GLRMask:     3,066,674
llguidance:  3,068,495
GLRMask had five samples at or above 50 µs and zero at or above 75 µs. llguidance had 17,787 samples at or above 500 µs, 864 at or above 1,000 µs, 366 at or above 2,000 µs, and 17 at or above 5,000 µs.
The reciprocal of mean constraint-only TBM is approximately 290,062 transitions/s for GLRMask and 47,242 transitions/s for llguidance. This is not end-to-end model throughput; it is only a convenient reciprocal service-time quantity.
TTFM / build distribution — official 9,558 only
TTFM:
| TTFM | GLRMask | llguidance |
|---|---|---|
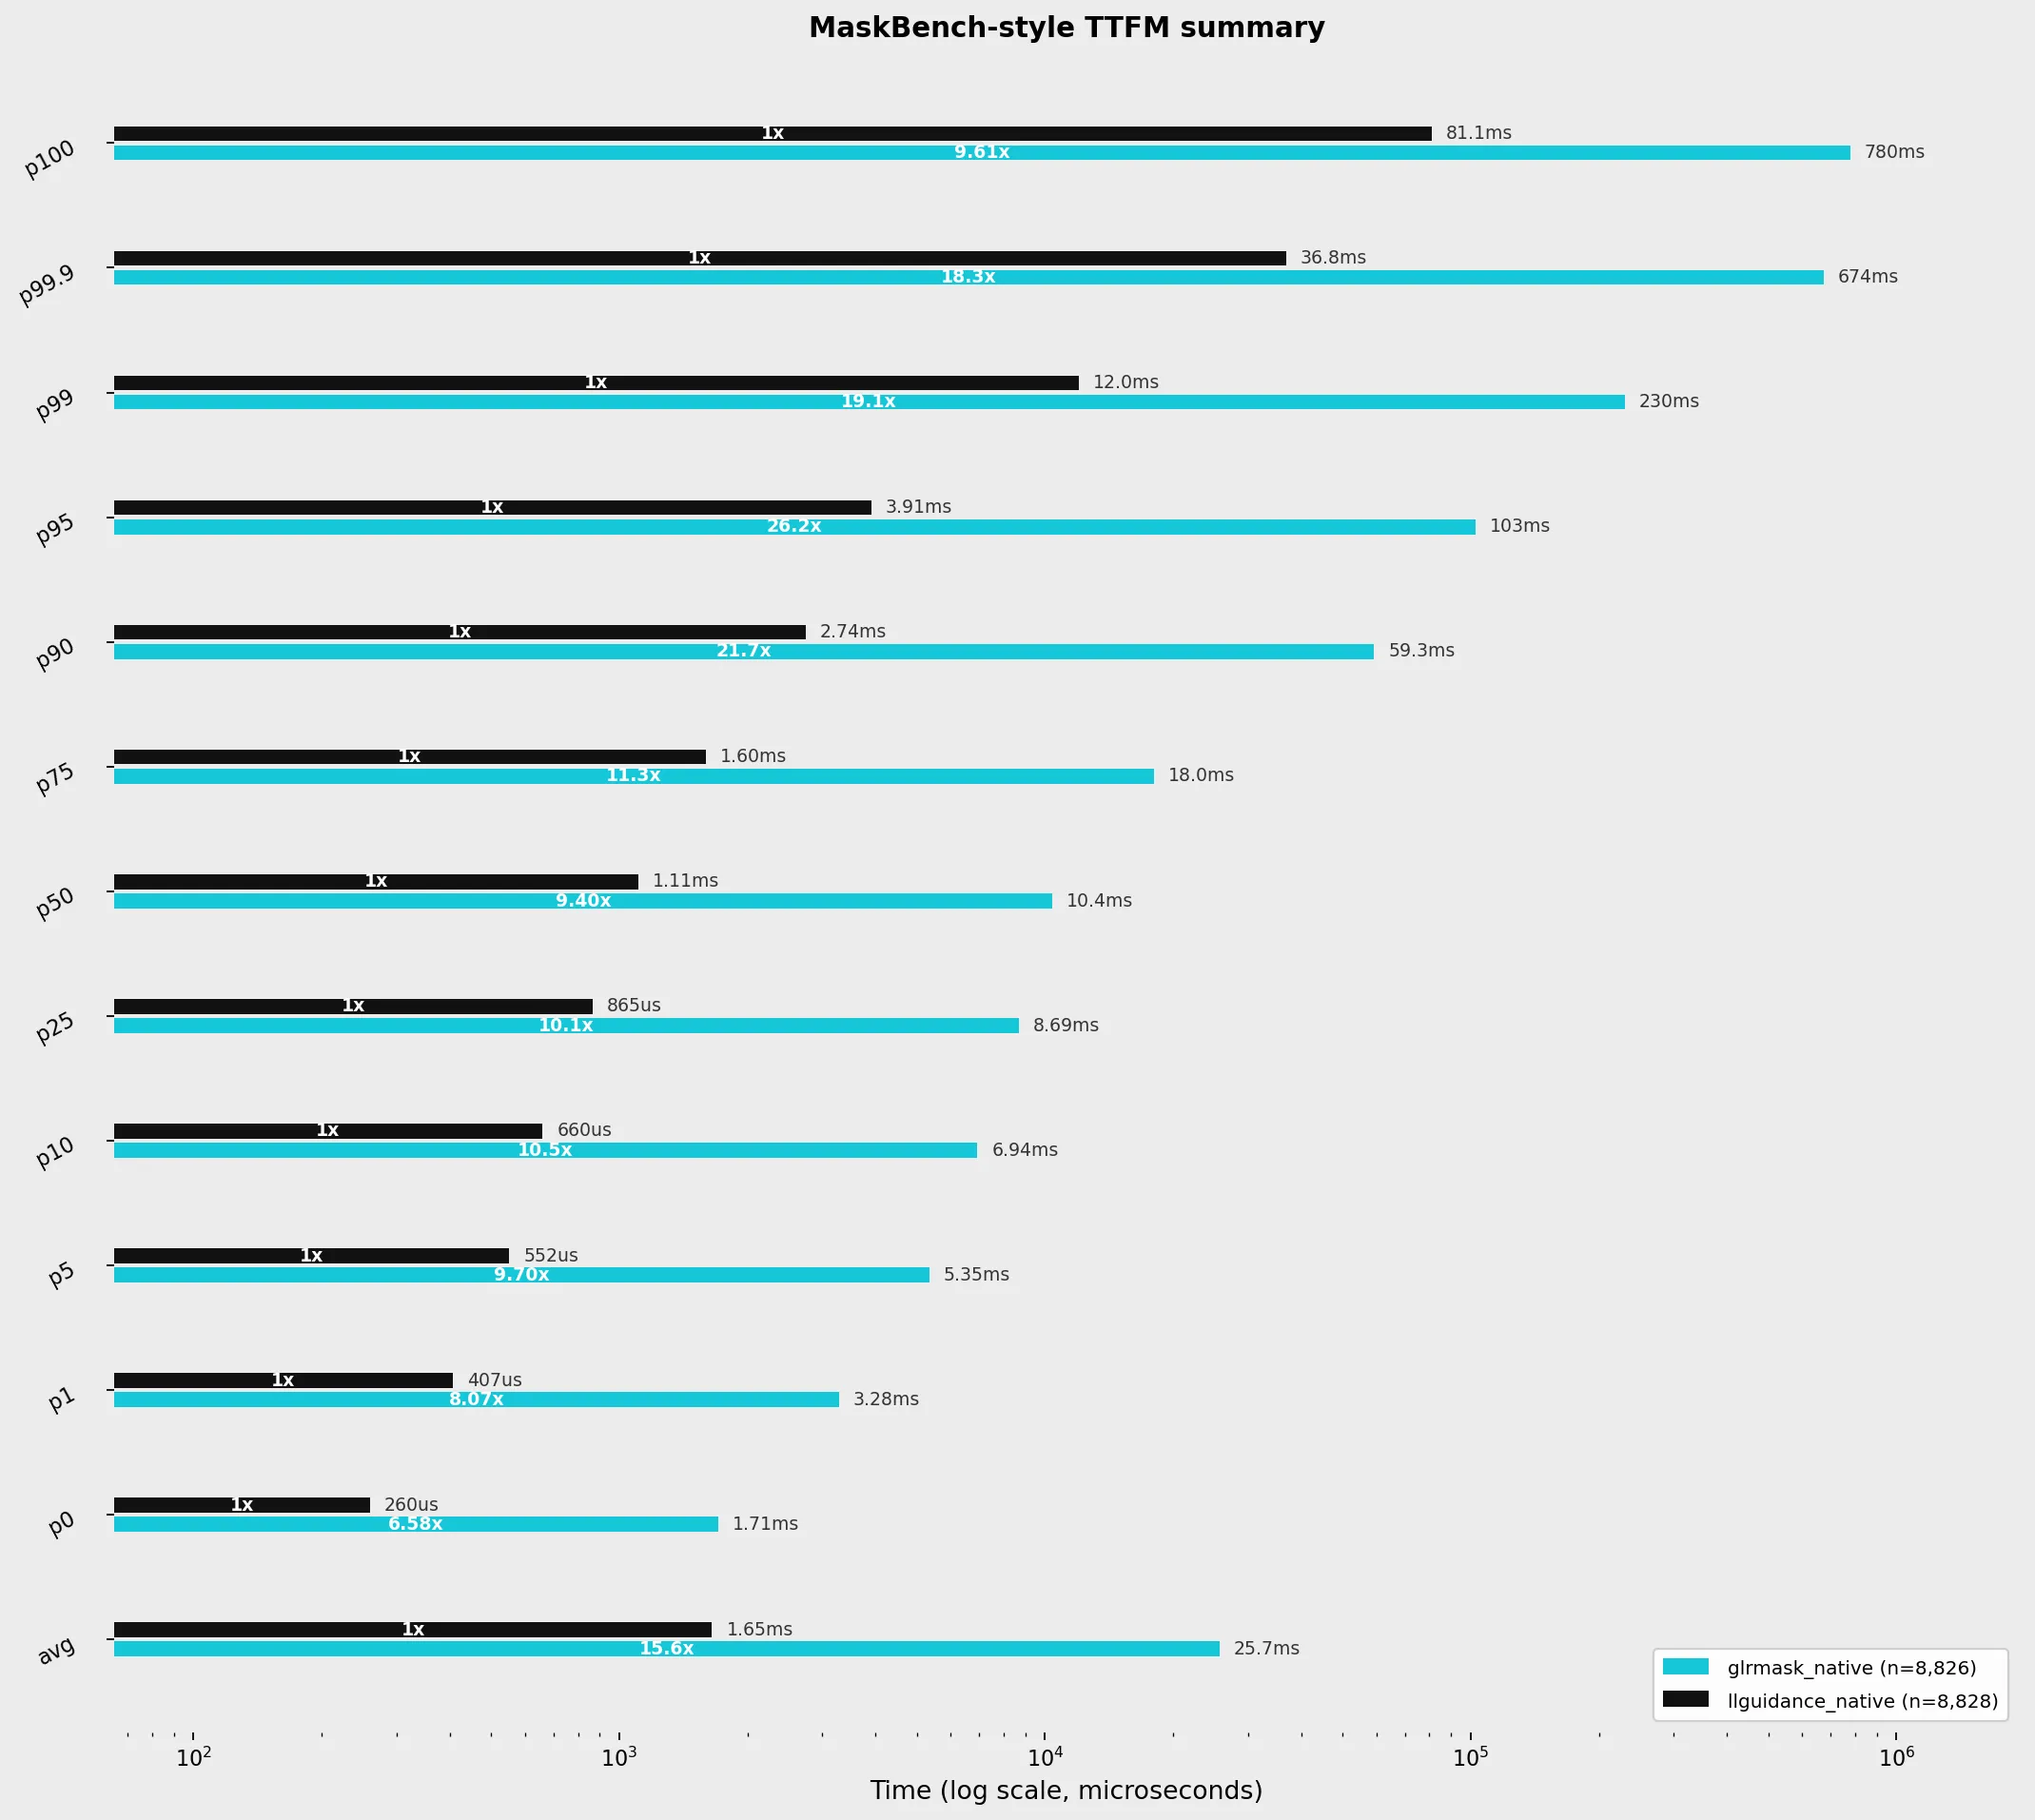
| mean | 25,737 µs | 1,652 µs |
| p50 | 10,421 µs | 1,109 µs |
| p90 | 59,350 µs | 2,738 µs |
| p95 | 102,590 µs | 3,909 µs |
| p99 | 229,809 µs | 12,023 µs |
| p99.9 | 674,319 µs | 36,839 µs |
| maximum | 779,588 µs | 81,104 µs |
Constraint build time itself is nearly identical to TTFM in this old CFA run:
| Build | GLRMask | llguidance |
|---|---|---|
| p50 | 10,417 µs | 1,062 µs |
| p90 | 59,346 µs | 2,715 µs |
| p99 | 229,809 µs | 11,946 µs |
| p99.9 | 674,317 µs | 36,832 µs |
| maximum | 779,586 µs | 81,104 µs |
The static GLRMask design is deliberately trading substantially more up-front compilation for a much smaller runtime tail.
Paired-problem tail incidence
Among the 7,970 paired runtime problems:
| Event observed in a problem | GLRMask | llguidance |
|---|---|---|
| any TBM ≥ 50 µs | 4 / 7,970 (0.0502%) | 7,967 / 7,970 (99.9624%) |
| any TBM ≥ 100 µs | 0 | 6,906 / 7,970 (86.6499%) |
| any TBM ≥ 200 µs | 0 | 1,952 / 7,970 (24.4918%) |
| any TBM ≥ 500 µs | 0 | 855 / 7,970 (10.7277%) |
| any TBM ≥ 1,000 µs | 0 | 142 / 7,970 (1.7817%) |
Interpretation limits
This result supersedes the July README figures, but it is not the final publication benchmark:
- The displayed population is correctly restricted to the 9,558 official JSONSchemaBench schemas, but the source timing chunks came from the older expanded CFA sweep.
- GLRMask build/TTFM remains from the original 12-vCPU M8azn run; selected fixed-code runtime timing was refreshed on a 4-vCPU M8azn machine from the same CPU family.
- The old CFA path uses a Python benchmark adapter and Linux thread-CPU timing. The October 8 native Rust run uses thread CPU TBM and wall BUILD/TTFM, as documented in the current Overview.
- The old CFA replay tokenizer is not the canonical real Hugging Face Llama-3.1 tokenizer used by the final native runner.
- This run used llguidance 1.6.1. The final native benchmark runner is pinned to llguidance 1.8.0 commit
dbaf504d498b6aeede06ae57adc6f7c2c4848c59.
The October 8 native 9,558-schema run is now available on the Overview. These historical values are not current release performance.
Figure provenance
The README figures are copied byte-for-byte from the current official-population plots in CFA’s canonical result directory:
docs/assets/benchmark-tbm-tail-2026-08-20.webp←c_tbm_tail_smooth_plot.webpdocs/assets/benchmark-tbm-2026-08-20.webp←b_maskbench_tbm.webpdocs/assets/benchmark-ttfm-2026-08-20.webp←a_maskbench_ttfm.webp
CFA preserves the previous expanded-population plots separately under plots/expanded-10263/; the current top-level plots and plots/official-jsb-9558/ use the 9,558 official schemas only.
Historical figures
Historical JavaScript evidence
The earlier Overview JavaScript arrays identify make example-js, grammar_glrm/js/js, 31 examples and 4,099 token steps, but omit the exact source revisions, clocks and repeat policy. Those arrays remain in the repository for investigation and are not presented as verified performance here. The August token-by-token investigation preserves the separately documented illustrative traces; it is historical, and does not qualify the October release source.